DocETL
Processes document collections with LLMs in steps that optimize themselves
Steal this
An LLM pipeline of map, reduce and filter steps that rewrites itself to run cheaper.
What it is
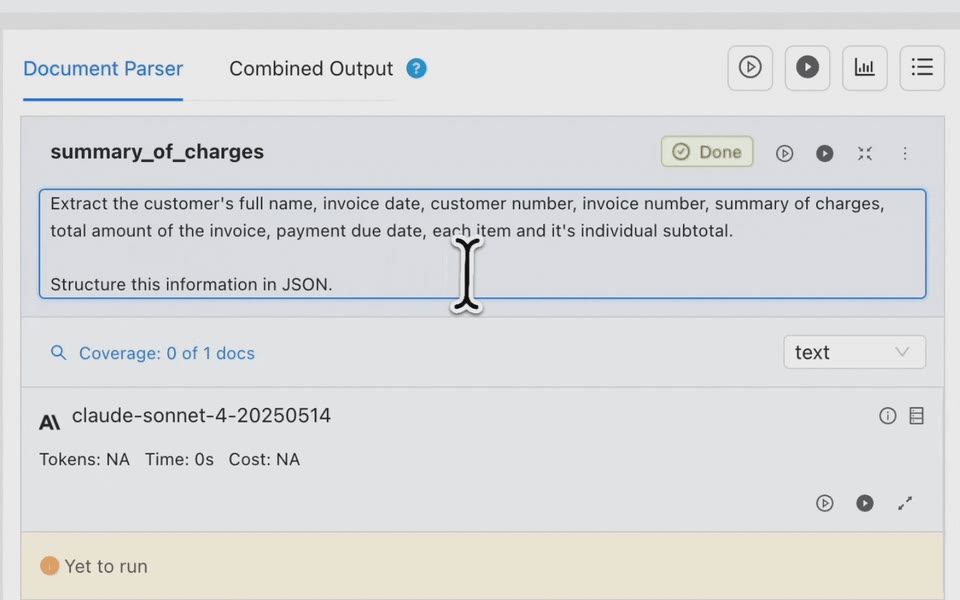
An open source system for processing large collections of data with LLMs. You write each operation in plain language (map, reduce, filter) and it runs them in parallel, optimizes the pipeline and returns tables.
What it’s for
For analyzing hundreds of documents with AI without wiring and tuning every call by hand.
Benefits
- Operations written in plain language
- Tunes models and prompts for cost and accuracy
- A Claude Code skill helps write the pipeline
Caveats
- Needs an API key from an LLM provider
- MIT license